Monday, 29 July 2013

Defensive coding : A Little effort to avoid a bug

Programmer's version of Murphy's law: Any code that can go wrong, will go wrong.

Defensive coding means you put a little bit of effort to think how your code will be used and when/where it can fail. Think of interfaces to your code. Then avoid the buggy situations. You think of where your code can fail while you write it. Test suites can help once your code takes some shape and also when you make changes to your API. 

An example: Suppose your code is returning an array or a collection. In the following code the list to be returned is initialised to an empty list. This helps to avoid a NullPointerException.How?

class SomeName
{
   ArrayList<String> values;
   
  public SomeName()
  {
     //List with 0 elements
     values = new ArrayList<String>();
  }//constructor 

   public void doWork()
  {
     //We do some work which generates an array.
   }//

   public String[] getResults()
   {
        return values;
   }//
}//class

If the list object was not initialised and it was not created, the calling code could fail. Suppose the calling code did this. The null value returned (if it was never set) would fail on list.size(). list would be null.

//Calling code
list = someNameObj.getResults();
for(int i = 0; i < list.size(); i++)
{
   //..............
}//for


If this is buried in tons of code with re-throws (does happen) then we have lost time tracking it. As trivial as this might seem, this scenario comes up frequently during reviews and even in standard APIs. A small foresight can avoid a nasty bug.  Defensive programming helps save time as you move forward in your project.

Sunday, 7 July 2013

Securing data on AppEngine datastore and other clouds. Encryption? Then what?

Recently there is a lot of discussion on programming sites about encrypting data on cloud environments like App Engine. This post is a Sunday evening rumination on the topic and a small experiment on the concept. Test code is available at the end of the post. 

Assuming the following,

1) You have decided to bear the extra computing to store encrypted data in your AppEngine datastore table.
2) You have decided to bear the extra space and computing that may be needed to subsequently process your encrypted data. After all you just don't want to store the data. You want to be able to access it on some query.

If we encrypt the stuff we are putting on to AppEngine like infrastructure, how do we compare data on tables to answer queries? A thought is to hash the data bytes too and store it in a shadow table. Then use a one dimensional pattern recognition algorithm to compare.


Hashing your data: Suppose you have 10 bytes of data. You encrypted it and put it on your AppEngine table. Hash the 10 bytes taking 2 consecutive bytes at a time. i.e if your data is say "abcdef" hash(a,b) then hash(b,c) and so on. Store this sequence of hash on another table possibly with a foreign key  reference. If you use MD5 hashing then, it mean you end up with 9 * 16 bytes of hash for 10 bytes of data. But as per the assumption you have decided to go this far to protect data on your cloud. This type of hashing (using signature of) 2 consecutive characters/bytes comes in Donald Knuth's art of programming book.


Comparing data now comes down to comparing the hashes generated above. Hashes of the same 2 bytes should match. So how similar are the two hashes can be answered by one dimensional pattern recognition? After hashing the original table data and input data, we have 2 byte sequences with negative, positive and zero values. They can be compared by finding the maximum contiguous sum on each byte sequence.  If the two sums are same or near then the underlying data is also same or similar. This throws up the question of what does 'near' mean.

A small test: We have two strings. We generate a hash for each of the strings. The hash is a sequence of bytes. It is obtained by applying MD5 hash on every 2 consecutive bytes of the strings. From the output we can see that this could work. But, how to compare two byte sequences and its implementation on the underlying database also comes into question.

Snapshot of hashing code is here. This type of using signatures for document matching is mentioned in Knuth's art of programming.

Snapshot of finding maximum contiguous sum in a byte array

Complete source code is available here.
https://drive.google.com/folderview?id=0BxhHg0qy5gi4SzVWdXJfS2NGOWs&usp=sharing

Sample input strings
Sample output
So maybe we can have a secure library for Appengine? What about comparison operators like < & >?

Thursday, 4 July 2013

Android UI: Scrollable Edit text with OK Cancel Buttons at the bottom

This post is part of the Android UI series. While designing my app I was searching for a GUI which had a) an edit box where user can type in stuff. More than one line i.e a multi line edit text box. b) The edit text box is scrollable c) A bottom panel or footer of 2 buttons which can say OK or Cancel.

One unique requirement I have seen on stackoverflow is this edit text box to grow as much as possible but stops short of blocking the panel of buttons. i.e the buttons will be shown irrespective of the amount of text in the box.The UI needed is as show below.

a) UI with buttons panel. Edit Text has not filled the view adequately.

b) UI with scrollable Edit Text and Button panel. Text box has a lot of content but will not block the Button panel.

The layout is as follows
<RelativeLayout xmlns:android="http://schemas.android.com/apk/res/android"
              xmlns:tools="http://schemas.android.com/tools"
              android:layout_width="match_parent"
             android:layout_height="match_parent" >
    <LinearLayout
          android:orientation="vertical"
          android:layout_width="fill_parent"
          android:layout_height="wrap_content">
         
        <LinearLayout
              android:layout_width="fill_parent"
              android:layout_height="wrap_content"
            android:orientation="horizontal">
       
        <TextView
               android:id="@+id/note_taker_title_prompt"
               android:layout_width="wrap_content"
               android:layout_height="wrap_content"
               android:paddingLeft="6dip"
              android:paddingRight="6dip"
              android:paddingTop="6dip"
               android:text="@string/note_taker_title_prompt" />
           
            <EditText
                android:id="@+id/notetaker_title_et"
                android:layout_width="match_parent"
                android:layout_height="wrap_content"
                android:layout_marginBottom="4dp"
                android:layout_marginLeft="4dp"
                android:layout_marginRight="4dp"
                android:layout_marginTop="16dp"
                android:gravity="center"
                android:singleLine="true" />
        </LinearLayout>
       
   <LinearLayout
          android:orientation="vertical"
          android:layout_width="fill_parent"
          android:layout_height="wrap_content">
       
        <EditText
            android:id="@+id/notetaker_text_et"
            android:layout_width="match_parent"
            android:layout_height="wrap_content"
            android:scrollHorizontally="false"
            android:scrollbars="vertical"
            android:layout_weight="1"
            android:layout_marginBottom="4dp"
            android:layout_marginLeft="4dp"
            android:layout_marginRight="4dp"
            android:layout_marginTop="16dp"
            android:singleLine="false" />
   
            <LinearLayout
                      android:layout_width="fill_parent"
                      android:layout_height="wrap_content"
                      android:orientation="vertical"
                      android:gravity="center">
              <View
                      android:layout_width="match_parent"
                   android:layout_height="1dip"
                   android:background="#393b3e"
                   android:layout_alignParentTop="true"/>
                 <LinearLayout
                    android:layout_width="fill_parent"
                    android:layout_height="wrap_content"
                    android:gravity="center_vertical"
                    android:orientation="horizontal">

                    <Button
                        android:id="@+id/notetaker_cancel_btn"
                        style="?android:attr/borderlessButtonStyle"
                        android:layout_width="wrap_content"
                        android:layout_height="wrap_content"
                        android:layout_gravity="center_horizontal"
                        android:layout_weight="1"
                        android:gravity="center"
                        android:paddingLeft="6dip"
                        android:paddingRight="6dip"
                        android:paddingTop="6dip"
                        android:text="@string/get_btn_back" />

                     <View
                        android:layout_width="1dip"
                        android:layout_height="match_parent"
                        android:background="#393b3e"
                        android:layout_centerHorizontal="true"/>

                    <Button
                        android:id="@+id/notetaker_save_btn"
                        style="?android:attr/borderlessButtonStyle"
                        android:layout_width="wrap_content"
                        android:layout_height="wrap_content"
                        android:layout_gravity="center_horizontal"
                        android:layout_weight="1"
                        android:gravity="center"
                        android:paddingLeft="6dip"
                        android:paddingRight="6dip"
                        android:paddingTop="6dip"
                        android:text="@string/note_taker_save_btn" />

                    </LinearLayout>
                   
                <View android:layout_width="match_parent"
                         android:layout_height="1dip"
                         android:background="#393b3e"
                         android:layout_alignParentBottom="true"/>   
        </LinearLayout>
        </LinearLayout>   
</LinearLayout>
</RelativeLayout>

Android UI: Flat Halo dark buttons like Sony Xperia ion

This is also part of the Android UI series. Here we see how to get the look and feel of the black Halo flat buttons seen on Sony ion or Xperia phones. Quite good looking buttons.

The objective UI is as follows. Notice the Back button at the bottom.

The layout xml for this button is as follows.
<?xml version="1.0" encoding="utf-8"?>   
        <LinearLayout
                android:id="@+id/about_footerlayout"
                android:layout_marginTop="3dip"
                android:layout_height="wrap_content"
                android:orientation="vertical"
                android:layout_width="fill_parent"
                android:gravity="center">
                <View
                    android:layout_width="match_parent"
                    android:layout_height="1dip"
                    android:background="#393b3e"
                    android:layout_alignParentTop="true"
                />
                <Button
                    android:id="@+id/about_back_btn"
                    style="?android:attr/borderlessButtonStyle"
                    android:layout_width="match_parent"
                    android:layout_height="wrap_content"
                    android:layout_gravity="center_horizontal"
                    android:gravity="center"
                    android:paddingBottom="6dip"
                    android:paddingLeft="6dip"
                    android:paddingRight="6dip"
                    android:paddingTop="6dip"
                    android:text="@string/get_btn_back" />
        </LinearLayout>

Android UI: Activity to show a license agreement

This post is also part of the Android series. Here we see a way to show license agreements on android UI with OK Cancel or Accept Reject buttons at the bottom. The license text ofcourse is scrollable and must occupy the left over space. We also throw in a check box for the user to disable the screen after reading/accepting the agreement.

The end UI looks like this
The layout Xml file is as follows. Notice the textview inside scroll view and the checkbox. There are suggestions on web to not use LinearLayout in a nested fashion. But, this one works quite well and is reasonably fast on a virtual device too.

<LinearLayout xmlns:android="http://schemas.android.com/apk/res/android"
        xmlns:tools="http://schemas.android.com/tools"
        android:orientation="vertical"
        android:layout_width="fill_parent"
        android:layout_height="match_parent">
  
        <ScrollView
                android:id="@+id/license_agree_scrollView"
                android:layout_width="fill_parent"
                android:layout_height="wrap_content"
                android:layout_weight="1"
                android:fillViewport="true">
           
                    <TextView
                        android:id="@+id/license_agree_textview"
                        android:layout_width="match_parent"
                        android:layout_height="match_parent"
                        android:paddingLeft="6dip"
                        android:paddingRight="6dip"
                        android:paddingTop="6dip" />
            </ScrollView>
   
    <LinearLayout
        android:orientation="vertical"
        android:layout_width="fill_parent"
        android:layout_height="wrap_content">
   
          <LinearLayout
            android:orientation="vertical"
            android:layout_width="fill_parent"
            android:layout_height="wrap_content">
            <View
                    android:layout_width="match_parent"
                    android:layout_height="1dip"
                    android:background="#393b3e"
                    android:layout_alignParentTop="true"/>
            <TextView
                android:id="@+id/license_agree_prompt"
                android:layout_width="match_parent"
                android:layout_height="wrap_content"
                android:paddingLeft="6dip"
                android:paddingRight="6dip"
                android:paddingTop="6dip"
                android:text="@string/license_accept_prompt" />
            <CheckBox
                android:id="@+id/license_agree_check_noshow"
                android:layout_width="match_parent"
                android:layout_height="wrap_content"
                android:text="@string/license_check_no_show_again" />
        </LinearLayout>
       
        <LinearLayout
                android:layout_width="fill_parent"
                android:layout_height="wrap_content"
                android:orientation="vertical"
                android:gravity="center_vertical">
                <View
                    android:layout_width="match_parent"
                    android:layout_height="1dip"
                    android:background="#393b3e"
                    android:layout_alignParentTop="true"/>
                
                        <LinearLayout
                        android:layout_width="fill_parent"
                        android:layout_height="wrap_content"
                        android:layout_weight="1"
                        android:gravity="center_vertical"
                        android:orientation="horizontal">   
                        
                            <Button
                                android:id="@+id/license_agree_reject"
                                style="?android:attr/borderlessButtonStyle"
                                android:layout_width="wrap_content"
                                android:layout_height="wrap_content"
                                android:layout_gravity="center_horizontal"
                                android:layout_weight="1"
                                android:gravity="center"
                                android:paddingBottom="6dip"
                                android:paddingLeft="6dip"
                                android:paddingRight="6dip"
                                android:paddingTop="6dip"
                                android:text="@string/license_agree_reject_btn" />

                             <View
                                android:layout_width="1dip"
                                android:layout_height="match_parent"
                                android:background="#393b3e"
                                android:layout_centerHorizontal="true"/>
                            
                            <Button
                                android:id="@+id/license_agree_accept"
                                style="?android:attr/borderlessButtonStyle"
                                android:layout_width="wrap_content"
                                android:layout_height="wrap_content"
                                android:layout_gravity="center_horizontal"
                                android:layout_weight="1"
                                android:gravity="center"
                                android:paddingBottom="6dip"
                                android:paddingLeft="6dip"
                                android:paddingRight="6dip"
                                android:paddingTop="6dip"
                                android:text="@string/license_agree_accept_btn" />

                         </LinearLayout>       
             <View
                    android:layout_width="match_parent"
                    android:layout_height="1dip"
                    android:background="#393b3e"
                    android:layout_alignParentBottom="true"/>   
        </LinearLayout>
    </LinearLayout>
</LinearLayout>


Android: How to show an activity as a dialog

This post is part of a series on Android UI nuances. After releasing my app on playstore I thought I would add my answers to the contributions on stackoverflow.

How do you make an activity behave like a dialog? For example the figure shows a dialog which is an activity.

a) Have your activity ready.
b) On your app's manifest file change the activity as shown below
c) Where DialogTheme is defined in your styles.xml file as follows

That is all to get an activity to behave like a dialog.

Saturday, 29 June 2013

Celatum for Android : Secure notes and GMail attachments

Celatum is, an Android application that I developed, is now available at Google Play Store. Celatum allows you to store and send secure notes using GMail attachments. Check it out ;-)

Get it on Google Play

* Read the document on how Celatum works
https://docs.google.com/file/d/0BxhHg0qy5gi4SWRiQ0JwRXU2RWc/edit?usp=sharing
* An FAQ is here
https://docs.google.com/file/d/0BxhHg0qy5gi4cnliX3YxV2s5UEU/edit?usp=sharing

Saturday, 8 June 2013

Hadoop Streaming in Python : Nuances & Sample

Hadoop streaming allows us to write mappers and reducers in languages like python, ruby and even C. Using python, the amount of code involved in writing a mapper and reducer is less compared to Java. Also, the streaming has some nuances to watch for.

1) Streaming works like Unix command line pipes. i.e data is written and read in text. Apart form the first input and last output, standard input and standard output are used. i.e your mapper in python does a print on its standard output and the reducer gets it on its standard input.

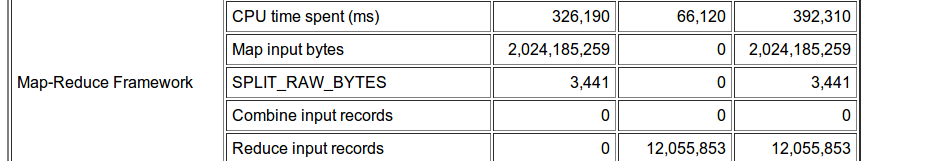
2) The mapper and reducer work on splits. Splits are the chunk of data that a mapper is given. It need not be the same as the HDFS chunk size. From observation it is seen that, this value changes as the program proceeds.

3) Streaming works on lines of input rather than (key, value) pairs. Although the notion of (key,value ) pairs can be used in streaming too. If you don't specify the (key, value) pairs and also the separator, defaults will be used. These are tab for the separator and the whole input line for key and an empty value. What this means to us developers is that, if you don't use/impose the notion of key value pairs, you do the sorting within a group in your reducer code. i.e when the whole line is used as key, your reducer may not necessarily receive the shuffled & sorted input it expects. When you write the mappers and reducers in Java your code actually receives the key value pair. Here you won't. So watch out for the sorting.

For this use the following parameters when running your streaming program.
-D stream.map.output.field.separator=, means "," is the separator used. Default is tab.
-D stream.num.map.output.key.fields=4 means all of the output line until the 4th separator is used as key and the rest as value.

4) Re-order the map outputs with the key parameter above to ensure grouping of input to reducer (as you want it to be).

5) Within your python code add #!/usr/bin/python at the very beginning to tell the program which interpreter to use for the mapper code and reducer code.

6) Check the mapper and reducer using the command line and sample data. If it works there, it should work on Hadoop. For example, this checks the working of a mapper and reducer written in python
cat ./datagen/small-earthquake.data | ./stream/mapper.py | sort | ./stream/reducer.py


Sample scenario: A 2GB file of earthquake information is available. Here, we write a mapper to filter the input and a reducer to do a count on the data it receives. File includes the following columns in order year, city name, quake magnitude, latitude, longitude. The mapper filters the input between years 1960 and 2000. The reducer counts the number of quakes for each city in that data.


The mapper  and reducer code in python are shown below

Notice that, the mapper rearranges the order of columns to <city, year> and tab is used as the separator since this is the default one. Plus, since city is the first column in map output, map output will be grouped on the basis of the first column i.e up until the first delimiter tab. Refer the nuances above.

Run the streaming command on Hadoop as follows:


hadoop jar ~/Development/hadoop-1.0.3/contrib/streaming/hadoop-streaming-1.0.3.jar \
-input /hadoop/streampython/large-earthquake.data \
-output  /hadoop/streampython/filtered \
-file ./stream/mapper.py \
-mapper 'mapper.py' \
-file ./stream/reducer.py  \
-reducer 'reducer.py'


Sample code: The git, eclipse project for this is available at this link. It also has a data gen script that, can generate 2GB plus test earthquake data.

https://drive.google.com/folderview?id=0B-oeIeog2xb7RWlpRDBROEdFT2c&usp=sharing

Screens:
a) Input files:

b) The SPLIT_RAW_BYTES for the map task.

c) Job Status with two reducers

Some Errors to watch out for:
1) You see the following on the job tracker -> Task tracker for you maps. Your maps seem to have been killed more times than allowed.


java.lang.RuntimeException: PipeMapRed.waitOutputThreads(): subprocess failed with code 2
 at org.apache.hadoop.streaming.PipeMapRed.waitOutputThreads(PipeMapRed.java:362)
 at org.apache.hadoop.streaming.PipeMapRed.mapRedFinished(PipeMapRed.java:576)
 at org.apache.hadoop.streaming.PipeMapper.close(PipeMapper.java:135)
 at org.apache.hadoop.mapred.MapRunner.run(MapRunner.java:57)
 at org.apache.hadoop.streaming.PipeMapRunner.run(PipeMapRunner.java:36)
 at org.apache.hadoop.mapred.MapTask.runOldMapper(MapTask.java:436)
 at org.apache.hadoop.mapred.MapTask.run(MapTask.java:372)
 at org.apache.hadoop.mapred.Child$4.run(Child.java:255)
 at java.security.AccessController.doPrivileged(Native Method)
 at javax.security.auth.Subject.doAs(Subject.java:416)
 at org.apache.hadoop.security.UserGroupInformation.doAs(UserGroupInformation.java:1121)
 at org.apache.hadoop.mapred.Child.main(Child.java:249)


For myself, this was due to the fact that, I had not added  #!/usr/bin/python to my python files. Once added, there were no issues. There was no need to change permissions on any files.

2) Basic Hadoop Nuances:

a) Add the following property to your core-site.xml. This tells hadoop which location to use for its tmp folder. A location that does not get modified over re-boots.

<property>
<name>hadoop.tmp.dir</name>
<value>/home/harisankar/Hadoop/tmp</value>
</property>

b) Add the following two properties to your hdfs-site.xml. These tell hadoop where to store its name node details and also the data chunks. You can see the data chunks for your files here.

        <property>
  <name>dfs.name.dir</name>
  <value>/home/harisankar/Hadoop/name</value>
</property>

<property>
  <name>dfs.data.dir</name>
  <value>/home/harisankar/Hadoop/data</value>
</property>

Otherwise your datanode and namenode playup after a re-boot. You may see exceptions like, could replicate to only 0 nodes and Data node's Connection to namenode timedout after n tries. in the log files.

Saturday, 18 May 2013

Knapsack 0/1 problem and algorithm: Implementation in Python, Dynamic programming and Memoization

This post is on the Knapsack algorithm which does the following. You have a list of items each with a value and weight. You have a total capacity as limit. You have to take as many items to increase value within the limit. A good example, similar to the one given by MIT Professor John Guttag (in open courseware) is, you break into a bank vault with a sack which can hold 100Kg of weight. You are faced with a pile of gold coins,  million dollar bonds, a huge stack of Marlboro cigarettes, stacks of red bull and Heineken. How much of each should you take  given your limit? A better example is you are going to Mars and your allotment in the shuttle is 400Kg and you have to take items that are valuable in that limit.

The Algorithm is recursive but, uses memoization to cut short the search through the solution tree. i.e for a pair (number of things remaining to take from, remaining capacity) i.e you have 5 more things to take from and weight limit is now 30Kg then, what do you take for this? If this is already solved in the recursion somewhere we use that, instead going down to that. This is where memoization comes in and Python dictionary is well suited for this. So, you have sub problems and find optimal solutions to those problems and solve the parent problem.

The result of the algorithm is a pair (V, I) where V is the accrued value of items we decided to take. I is the list of items we decided to take.

Knapsack 0/1 Algorithm Pseudo code:

knapsack(<L: list of items>, <W: weight limit now>, <S: solutions accumulated over sub-problems so far>)
{
        IF S is empty i.e first call THEN
           Initialize S the set/dictionary to hold solutions to sub-problems

       IF  combination of (L, W) is already in S THEN
           (V,I) for this sub-problem =  S(L, W)
       ELSE IF L is empty and W is 0 THEN
           (V, I) is (0, nothing)    
       ELSE IF we take the first item on list and its weight, when added, exceeds the limit THEN
              (V,I) = knapsack(L - first item at this call, W, S)
       ELSE
               /* What we do here is. We assume we take the first item. Then what is (V,I) for the remaining
                   walks. Also, what is the result (V,I) id we don't take the item at this point. Choose which
                   ever solution that maximises the value.
               */
               We assume we take the first item of the list.
                Let V1 = Value of first item + (V, I) for knapsack(L - first item, W - weight of first Item, S)
                We also find (V2, I) if we don't take the item.
                       i.e (V2, I) for knapsack(L - first item, W, S)
             
                IF V1 is better than V2 THEN
                       go with that result (V1, I)
                ELSE
                       go with the other result (V2, I)
       Add the corresponding result (V, I) to S
}

Sample with the following items. <Item Name, Weight, Value>

('Gold Biscuits', 20, 100)
('Heineken', 2, 30)
('Marlboro', 1, 10)
('Currency in $10 bills', 10, 10)
('Currency in 50$ bills', 45, 40)
('Million$ Govt Bonds', 1, 1000)
('Diamonds', 25, 80)
('Lays Chips', 1, 4)
('RedBull Cans', 20, 35)
('Predictions on WallStreet', 1, 200)
('Key Combination of Vault', 1, 200)
('Harry Potters List of real life Spells', 2, 1)

Sample Output: As you can see the program takes the things of value :))


Solution Python Code: Is available at
https://drive.google.com/folderview?id=0BxhHg0qy5gi4TkpuTHQ4OWZGYnc&usp=sharing

References:

1. MIT Open courseware on Introduction to Computer Science and Programming, Prof John Guttag

Monday, 13 May 2013

Quick Sort: Partition Algorithm

A post on quick sort is not particularly interesting for most developers. But, when you see more and more people using a complicated partitioning algorithm when explaining quick sort then, it is ok post a simpler partitioning algorithm. This algorithm and similar ones came in the Communications of the ACM and were retold by Bentley in his books. Still, they seem to be lost.
 
Quicksort works recursively by partitioning an array around a pivot element. So, after partitioning all the elements at indices less than the pivot's will be less the pivot itself. Those at indices greater than the pivot's index will be greater. Then, you repeat the same for elements on either side of the pivot. For example, if the array was 4, 19, 1, 3, 43, 45, 11, 2 and you say that, the pivot is 4 then, after partition around element 4, the array looks like this using this partition algorithm (explained further down).

2, 1, 3, 4, 43, 45, 11, 19

Then do quick sort on (2, 1, 3) 4 (43, 45, 11, 19). You get the idea.

So now comes the simpler partitioning algorithm. Here starting from the beginning
we keep track of elements greater than the pivot and whenever we see an element less than the pivot we replace the element which is greater than the pivot (we have it) with the one that is lesser.

So in our example if 4 was the pivot, 19 is the first element that is greater than the pivot, we go on to 1 and see that it is less than the pivot. We swap the two to get 4, 1, 19, 3, 43, 45, 11, 2. Now also we keep track of (index of) the first element that is greater than pivot. Again, we swap it for 3 and the array becomes 4, 1, 3, 19, 43, 45, 11, 2. Then, finally we meet 2 and then swap it for 19 and the array becomes 4, 1, 3, 2, 43, 45, 11, 19. So we have reached the end of the array. Our post condition is that, the pivot should be in such an index that, all elements to the left are less and those to the right are greater. This is achieved by simply swapping the pivot with our track index (here the index of 2). So we swap 4 and 2. Thus we get 2, 1, 3, 4, 43, 45, 11, 19.

Here is a snap of the partition code.
You can run the code in debug mode and see for yourself as to how this works.

The eclipse java project is available at theGoogle docs folder given below.

https://drive.google.com/folderview?id=0BxhHg0qy5gi4V2Q0ZlhrelZlOVU&usp=sharing

Tuesday, 7 May 2013

Google AppEngine: The network is becoming the computer

This post is a take on the Google AppEngine which is a cloud computing solution living in the Platform As a Service (PaaS) layer. A basic sample code is available at the end but, more concrete examples of this post are available on the resources mentioned in the reference section below.

Google AppEngine is Google's, to some extent free, web app execution environment for you. You can develop web applications and deploy it on AppEngine in an instant. You production execution environment is the offer. Traditionally, you design a webapp, the pages, middle tier and the database etc. You also have to install software for your production environment. With AppEngine, you just write the code and upload it. It will be available immediately on Google's infrastructure which you don't have to spend time and money on. On top of it all, is the ability to scale, replicate like Google.

In order to use AppEngine, you just need to signup on the AppEngine site with a email and password. If you have a Google account it is enough. The main applications that are suitable for AppEngine are the ones that require to talk to an HTTP(s) endpoint. Basically, web based applications like an online forum. You are restricted from doing traditional stuff like creating local files, opening outgoing sockets etc. But, you do have a lot of overwhelming options to add to your site like, email, instant messaging, distributed filesystem API, Memory caching, my favorite. You can develop using Python 2.7 which is what I used and also using Java, Google Go with corresponding SDKs from Google. There are number of web frameworks supported including Django. Here I followed the very basic webapp. 

If you have done servlet based development then, it is easy to get first hold of AppEngine. As always you have an application configuration file similar to web.xml. Here it is a .yaml file. My project's yaml file is shown below

You specify the script which will handle the requests to your server url. This script can be thought of as a controller servlet in Java Web programming using servlets. Then with in that python code, you create the application, specify the url mappings, the classes to handle the url mapping requests and you are basically done. So, in helloworld.py, I have the following similar to an MVC web app.

Also the code for the main handler as below, which has get and post to handle the request like servlets.

Set up on Ubuntu Linux:
1) Download the AppEngine Python sdk from Google. This is a zip file.
2) Extract it to say, /usr/local/appengine-python
3) Create links to appcfg.py and dev_appserver.py file in the above path at /usr/local/bin. So that, you can run these programs. This can be done using the command

 sudo ln -s /usr/local/google_appengine/appcfg.py /usr/local/bin/
4) Your folder /usr/local/bin will look something like this
5) Download the Eclipse plugin for AppEngine development and you are done. Although this is not necessary unless you use eclipse.

Uploading your project to AppEngine
1) Go to the root of you webapp project and execute the command as shown below. You will be asked a email and password for authentication and then your app will be provisioned instantly. You can access it at http://<appid when you created it on Appengine site>.appspot.com

2) The site on Google AppEngine
3) Download code for the project from link:
https://drive.google.com/folderview?id=0BxhHg0qy5gi4SFh6ejhBSFE2ZU0&usp=sharing

More explanations on code and features in next post.

Reference:
--------------
1) Core Python Applications Programming Chapter 12 on Google AppEngine.

Monday, 6 May 2013

Part 2 - Friend Suggestion like Facebook, Google+ or Product Suggestion like Amazon: Implementing for your own web app, site

In a previous post in the first half of 2012, I described how to roughly do a friend suggestion like Google or Facebook or item suggestion like Amazon. I am recalling the approach in that post before describing how to use machine learning to get better results. 

In the previous approach, we used to store vectors of user interaction on the hadoop file system. These vectors may include interaction between users or with the site. There we used MapReduce jobs to derive some meaning of the interactions and then using a weighted matrix to apply thresholds and priorities to arrive at the final result.

One thing that, I did not mention in that post is the use of machine learning libraries which have algorithms that can help in such scenarios. For example, Amazon uses machine learning techniques to show you Product recommendations. The counts we described in the previous post are crude although not completely off the chart. This is also used (in addition to proprietary algorithms, Facebook is coming up with a Graph search and algorithms on top of that could possibly make this easy) by Facebook / Linkedin to suggest 'you may know this person' type of recommendations. The focus of this post is that, we should use machine learning libraries to process interaction patterns and arrive at results. 

Input: We imagine that, we have large logs of user interactions, user likes (Facebook), Following items (Google plus) etc at some place on a Hadoop cluster. The best thing would be to use HBase as it is column oriented and is supposedly used at Facebook. Some examples can be user viewed another profile, user likes a movie, user viewed a video of a particular type, user changed his home town. All sorts of interactions. Labels and tags are used to aid this (remember the tags on videos in YouTube and labels on blogger posts!). 

Basically for every interaction or relation we can call it a dimension. For example, viewing another users profile is a dimension. Likes on movies is a dimension. Watching a video of a particular type say 'of Lady Gaga' is a vector in a dimension. Once we have these interaction vectors, we can find what is the affinity of the user in that dimension or type. A good place to start for finding affinity is the percentage frequency count or better the percentage frequency in a particular time period, the latter being more relevant. For example by using MapReduce on the interaction logs on Hadoop, we can arrive at numbers saying that, for the last day userA watched 4 videos tagged with 'Lady Gaga' and viewed profiles of 20 users in Washington D.C area. Such vectors are easy to generate. Refer the 'Hadoop Definitive guide' Tom White's book which has examples similar to this on earthquake data for the US. In a way you don't need to store as logs, you can directly feed the interaction vectors to HBase since it is column oriented ! But, you still need to derive a basic meaning out of the interactions before feeding them to machine learning.

Machine learning can be used to classify, cluster and some other stuff too. Here we are interested in these. Item Recommendations, Clustering and User Neighborhoods are a good place to start when you want to analyse user behavior. Clustering is useful when you want an overall view across all dimensions/vectors we discussed. So, the vectors from the MapReduce jobs are fed to machine learning which gives you results like userA is in neighborhood of userB, userA may like  itemC since he/she is in the same neighborhood as userB, in movies/movie likes dimension userA is similar to userB etc. You can refer to 'Mahout in Action By Sean Owen' on how to get going with this. Sample code in Chapters will be helpful. 

So all together the new approach looks similar to the case studies mentioned in Tom White's book.

Logs /HBase data -> Map Reduce -> Machine Learning -> Recommendations -> Store to RDBMS for provisioning. 

This seems a better way for item recommendations and the like compared to the previous post. More ways on how to this are available online. 

References
--------------
https://www.youtube.com/watch?v=kI4YIYInou0
https://www.youtube.com/watch?v=9A0PnPvQks4
Hadoop the definitive guide - Tom White (Book & code)
Mahout in Action - Sean Owen and team (Book)

Monday, 8 April 2013

Programming for Social Media : Twitter : Reading Tweets using python

Just to bring the aspect of search, social media into perspective before the post: 

Todays ACM technews has an article from Eberly College of Science relating to tweets analysis relating to a particular vaccine. It is available at 
http://science.psu.edu/news-and-events/2013-news/Salathe4-2013 Tweets were analysed for terms relating to the vaccine/vaccination. Then, user opinion was deduced. This is an example of using social media to derive trends or responses or acceptance.

As another example of impact of internet search: Earlier in December, during an informal Big Data meetup involving, Ministry of Health, Visa and SingTel, the head of MoH software division commented that, Google could find out if, there would be an outbreak of a particular disease say a flu in a particular region. This is due to the fact that, people would be searching for medicines, symptoms, prevention etc on Google. This could be analyzed to deduce what health issues are more prevalent in a particular region. 

Thinking on that line, Google does not know if, you actually bought the medicine or anything after a search. Whereas Amazon or eBay knows what you bought but, does not know if, you bought the item after a search or your affinity for that item. Standing out is Facebook which knows everything about you and your friends but, does not have the above two factors.

That said here is a small program that, demonstrates Python Twitter API. This retrieves tweets on an interesting subject and processes them. The tags in each tweet are counted and displayed in ascending order. For example, if #Tottenham appears 20 times and  #OldTrafford appears 40 times in the tweet stream, then it comes up in the list. Basically, a measure of what people are dicussing and how popular the topic is with the public.

Objective: Retrieve tweets with "premierleague" on it. Then find the most popular tags. Basically you can search for any key word.

Language used Python 2.7 and Twython for Twitter interface. Operating system Ubuntu 12.04. 

Twython API core code snapshot for Twitter


Sample Screen run on keyword "premierleague". (Printing tag counts by minute rather than by hour so that, output is available frequently)


The complete eclipse python project is available here as zip. You will need a postgresql database and Twython installed. The database table format is available here. You can also run TaTwitterQn/TwitterSearcher.py without the database to get tweets and show the tag counts.

Project Link:
https://docs.google.com/file/d/0B-oeIeog2xb7WDRFLUdzM0w0cEE/edit?usp=sharing

Some Issues/observations developing this program: https://github.com/ryanmcgrath/twython/tree/master/core_examples

1) Tweepy a popular Twitter API for python returns an 401 failure for search / filter operations. This is on the latest version of Tweepy from Git. But, tweepy has streaming api.

2) python-twitter seems to be a good api but, does not authenticate at times and also some of the documented parts do not seem to work. For example, the getHashTags part of the Tweets API does not work.

3) The same program can be coded in Java but, the effort would be more and the code size too. Python on the other hands was small and easy. If you already have a Java environment like Hadoop running then, it seems ok.

References:
1) https://github.com/ryanmcgrath/twython/tree/master/core_examples This is a good list of examples to use twython and you can get started to do your own programs easily.

Sunday, 31 March 2013

ANTLR 4.0

If you do use Google Analytics, you may have noticed that, the API is available for developers to use. Also, on a Youtube video showing "Google Analytics End to End", the engineers show 2 ways that developers can interact with Google Analytics. One is through an API that Google has exposed for developers to use. The second is a small edit box where you can type in the metrics / filters and you click on a button and you get the results based on the filters you mentioned.

Typing things in an English like question / expression which is not exactly sql but, will get you the results you are looking for does come in handy especially since, ordinary users can interface with your system easily. This is conceptually same as the Interactive Shop Finder in malls except that, you type in the question you are looking for. Users will be able to relate to this kind of interface as they will be able to test drive your software. 

Considering that, you need to cook up an expression / question that you will take from the user, parse that and get the results; means you need a small language that will allow your users to express themselves. This may have you filters as pre-defined keywords. For example, ga.City = Pasadena and ga.Country = USA is similar to what Google gives you. 

ANother Tool for Language Recognition will allow you to specify the Backus Naur Form of your small language and build you a parser. So all you have to do is;

u
1) Use ANTLR to specify the BNF of your small language
2) Get the parser for your language using ANTLR.
3) Use the parser to parse the user question
4) Catch the elements in the question that makes sense to you. i.e walk the expression tree. This is possible by assigning labels to your grammar rules. This is extremely helpful when you are walking the tree.
5) Build the real query that your database takes and get the result.


References:

ANTLR website has a lot of examples, and the BNF of the mainstream languages like Java and the like. So developers can hit the ground running designing their own small languages.

Sunday, 23 December 2012

Data Analytics : Hatari !

Embedding Pig in Python - Hatari!
---------------------------------------------
Pig Latin does not allow control structures like Java and other high-level languages. So inorder to get more control over the execution context, loop through a set of parameters etc we can embedd Pig in Python. This is supported only for Python 2.7 and not above. At first this may seem not so useful. But, if you have a single script, i.e a parameterised pig script like the one in the previous post, you can attach parameters to the script from Python. Plus since Python can also be used to write User Defined Functions, all the code Pig, Python, UDFs reside in the same project. This is usefull when things get more complex. In the previous post note that, I used a java project to create a java UDF which was used in Pig. So I had 2 deployments a pig script and a Java jar. But, if we embedd pig in python, we have only one deployment, the python code.

1) Write pig script in a file.
2) Use compileFromFile() function to load and compile your script. 
3) Bind using your list of map of parameters. yes a list of map of parameters.
4) Run the script using runSingle()
5) Get status on how things went using runSingle(). You can also use isSuccessFul().

Better yet Do this again for all your scripts. You can even read parameters from a file, add threading where each thread will execute a script with one set of parameters.

Source code with an example is available here

Ref: More details can be found in the presentation at http://www.slideshare.net/julienledem/presentation-pig-scripting by Julien Le Dem.

Ref: Good Read Chapter 9 on Book, Programming Pig by Alan F Gates